Revops dashboard design: fix crm data quality
Learn how RevOps dashboard design directly impacts CRM data quality — with actionable frameworks solo GTM engineers use to build dashboards that surface bad data before it derails pipeline forecasts.
RevOps Dashboard Design for CRM Data Quality
A proper revops dashboard design crm data quality system catches missing fields, duplicates, and stale records before they poison your reports. Most teams skip this step and wonder why their forecasting looks like a guessing game. The fix is not more dashboards. It is a dashboard built specifically to find broken data, paired with automated enforcement rules that prevent it from coming back. This is a practical walkthrough from someone who has shipped over 100 automations across HubSpot, Salesforce, and Clay-based enrichment flows.
The Problem: Your CRM Is Lying to You
Here is what I see week after week when I audit a company's CRM. The pipeline dashboard shows . When I drill into the records, 40% of them have no close date. Another 25% are missing company size. Five percent are duplicates created by different SDRs calling the same prospect. The forecast is not just optimistic. It is structurally broken.
This happens for three reasons:
The cost is not abstract. Bad data causes misallocated SDR time, wrong territory assignments, inflated pipeline, and lost deal credit. I once saw a VP miss a revenue target by because duplicate accounts hid real demand from the forecast model. That is not a data problem. That is a business problem wearing a data costume.
Layer One: The Health Dashboard
The framework I use at Systems by Sami has three layers. Each layer solves a specific failure mode in the CRM data lifecycle.
Layer Two: Automated Cleanup Pipelines
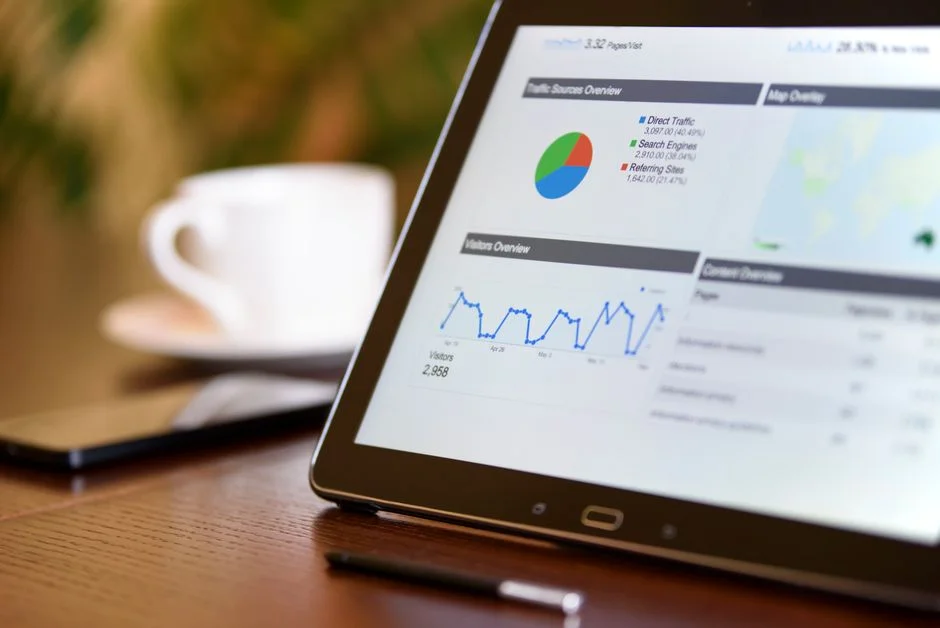
This is a single dashboard view that scores every record in your CRM on data quality. It tracks completeness percentage, duplicate risk, staleness, and enrichment coverage. You can build it in HubSpot with custom analytics dashboards or in a tool like Apollo or Clay with scheduled export jobs. The point is that someone, somewhere, is looking at a every week. Not revenue. Health.
Layer Three: Governance Rules
Clean data does not maintain itself. You need automated workflows that trigger on every new record and every record update. Common cleanup actions include deduplication matching, required field enforcement, company name standardization, and enrichment gap filling. These run in , HubSpot workflows, or Clay. The key is that the automation does not ask humans to fix things. It fixes things or creates tasks for the right owner.
Automation without governance creates automated messes. You need clear rules: what fields are mandatory, what enrichment source is authoritative, what counts as a valid duplicate, and what happens when the system cannot auto-resolve a conflict. These rules become the operating manual for your RevOps practice. Without them, every cleanup project becomes a one-off firefight.
Step One: Map Your Critical Fields
Here is the exact build sequence I follow when a client hires me to fix their CRM data quality through dashboard design.
Step Two: Build the Health Dashboard in HubSpot
Before you touch any tool, write down which CRM fields directly impact pipeline accuracy. For a typical B2B SaaS company these are:
Step Three: Set Up Deduplication with Clay
Everything else is noise. Focus your dashboard on these seven fields first.
Step Four: Automate Required Field Enforcement
If you are on HubSpot, create a custom report with these metrics:
Step Five: Schedule Monthly Data Audits
Pin this as the top dashboard widget. Name it . Make it the first thing anyone opening the CRM sees. If you are not on HubSpot, replicate this in Google Sheets with a weekly Clay export or in a dedicated analytics tool.
Clay is the most reliable tool I have found for deduplication at scale. Here is the setup:
This runs weekly. The output is a simple list: I have processed 50,000 records through this flow in a single run for under .
Create an n8n workflow that triggers on new CRM record creation and updated records. The workflow should:
This is the automation layer that actually changes behavior. Workflows solve it.
Build one final workflow that runs monthly and produces a data quality audit report. This report should include the health dashboard scores from the previous month, the number of duplicates merged, the enrichment coverage change, and any new critical field failures. Send it to the GTM leadership team every first Monday of the month. This creates accountability that does not rely on memory or ad hoc requests.
Cost Analysis: What This Actually Costs
| Component | Tool | Monthly Cost | Setup Time |
|---|---|---|---|
| CRM platform (HubSpot Professional) | HubSpot | $800/month | Already owned |
| Deduplication and enrichment | Clay | $120/month | 3 days |
| Workflow automation | n8n (self-hosted) | $20/month | 5 days |
| Apollo lead enrichment | Apollo | $200/month | 2 days |
| Dashboard analytics | HubSpot native + custom reports | $0 incremental | 2 days |
| Consulting and build time | Sami @ Systems by Sami | One-time $5,000-$8,000 | 2-3 weeks |
Building a revops dashboard design crm data quality system is not free. But it is dramatically cheaper than operating with bad data. Here is the real cost breakdown based on recent client projects.
Total monthly recurring cost: . Total setup timeline: . One-time build cost: if you hire a RevOps engineer. If you build it yourself with guidance, the time investment is 40 to 60 hours over three weeks.
Compare this to the cost of bad data. A single misforecasted quarter based on incomplete pipeline can cost . The payback period for this system is typically under 60 days.
What This Is NOT For
I want to be clear about who this approach does not serve. Credibility requires disqualification.
At that stage, you have 500 contacts or fewer. Manual cleanup takes 30 minutes. Automation overhead exceeds the problem size. Do not buy Clay and n8n. Just fix the data yourself.
If your leadership team cannot agree on what data matters, no dashboard will help. The framework assumes you can commit to a minimal set of critical fields. If you cannot, stop and solve that conversation first.
Automation enforces structure. It does not teach reps why data matters. You still need leadership to communicate that data quality is a revenue responsibility, not an administrative one.
Salesforce has significantly more complex deduplication logic and workflow architecture. The principles are the same, but the build timeline doubles and the tooling costs increase by 40%. If you are on Salesforce and have no dedicated RevOps person, hire one before building anything.
Data quality is a continuous operation. The dashboard you build today will need recalibration every quarter as your CRM schema evolves. If you are looking for a set-and-forget solution, this is not it. No one is.
What You Should Do Next
Here is the decision. If your CRM has more than , you need this system. The data is already corrupting your pipeline. Every day without it costs you forecast accuracy and rep productivity.